“No space left on device” can mean exhausted bytes, inodes, quota or a different filesystem than the one you checked. Diagnose the constraint before deleting logs or backups.
1. Find the affected mount
These read-only commands target GNU/Linux:
Code:
df -hT
df -i
findmnt -T /var/log
Replace /var/log with the directory where writes fail. A separate /var, container layer or network mount may be full while / has space. Check the application user's quota if the filesystem has room. Reserved blocks can make space unavailable to an ordinary service account.
2. Measure usage without crossing mounts
Code:
sudo du -xhd1 /var
sudo du -xhd1 /var/log
sudo journalctl --disk-usage
The -x option keeps the walk on one filesystem; -d1 summarizes one directory level. On a busy host, scans can cause I/O, so inspect one plausible directory at a time. Check application uploads, backup retention, caches and database logs. Hidden directories count too; a shell wildcard can miss them.
3. Explain a df/du mismatch
A removed file can still occupy space while a process holds it open. If lsof is installed:
Code:
sudo lsof +L1
Inspect the process and mount associated with large deleted files. Arrange a supported log reopen or targeted service restart after assessing impact. Do not kill processes blindly. Other differences include snapshots, filesystem metadata, sparse files, inaccessible directories and files hidden beneath mount points.
4. Reclaim the right data
Preserve incident evidence and verified backups first. Use the application's supported cache/log retention mechanism. Preview package or container cleanup and understand what it removes; Docker volumes can contain the only database copy. Never delete active database files or blindly run broad recursive removal commands.
If inodes are exhausted, investigate directories containing very many tiny files and fix their retention. If bytes are exhausted, identify the largest growing sources. Deleting one old archive without fixing an endless log loop buys only temporary relief. Avoid manually truncating a log when the application expects a different rotation process.
5. Validate recovery and prevent recurrence
Repeat df -h and df -i for the affected path, confirm the service can write, and check for database/application errors caused by the outage. Alert on both byte and inode availability with enough lead time. Budget local backup staging and update space. Track growth rather than relying on a single percentage threshold.
When asking for help: Share the failing path, filesystem type and sanitized df/du summaries. Avoid exposing customer filenames or secrets. If a filesystem turned read-only, inspect kernel/storage errors; deleting files is not the appropriate fix.
Reference:df manual and your installed man du/man lsof documentation. aaPanel lab walkthrough: storage checks and a deleted-open-file demonstration Verified 14 October 2026 on aaPanel Free 8.0.7 and Ubuntu 22.04.5. This extends the Linux procedure above with original lab measurements. The server had available space; we did not fill its disk or reproduce a disk-full outage.
A. Start from the path that could not be written
Check aaPanel Home's disk indicator as an initial clue, then use a private SSH or panel Terminal session to inspect the actual application, database, backup or temporary path. A headline root-disk percentage does not identify every separate filesystem.
For a website issue, match the failed operation with the access/error/application logs. Distinguish an exhausted resource from permission denial or a filesystem that became read-only before choosing a repair.
B. Check bytes and inodes for the relevant paths
Our read-only checks were:
Code:
df -h / /www /tmp
df -i / /www /tmp
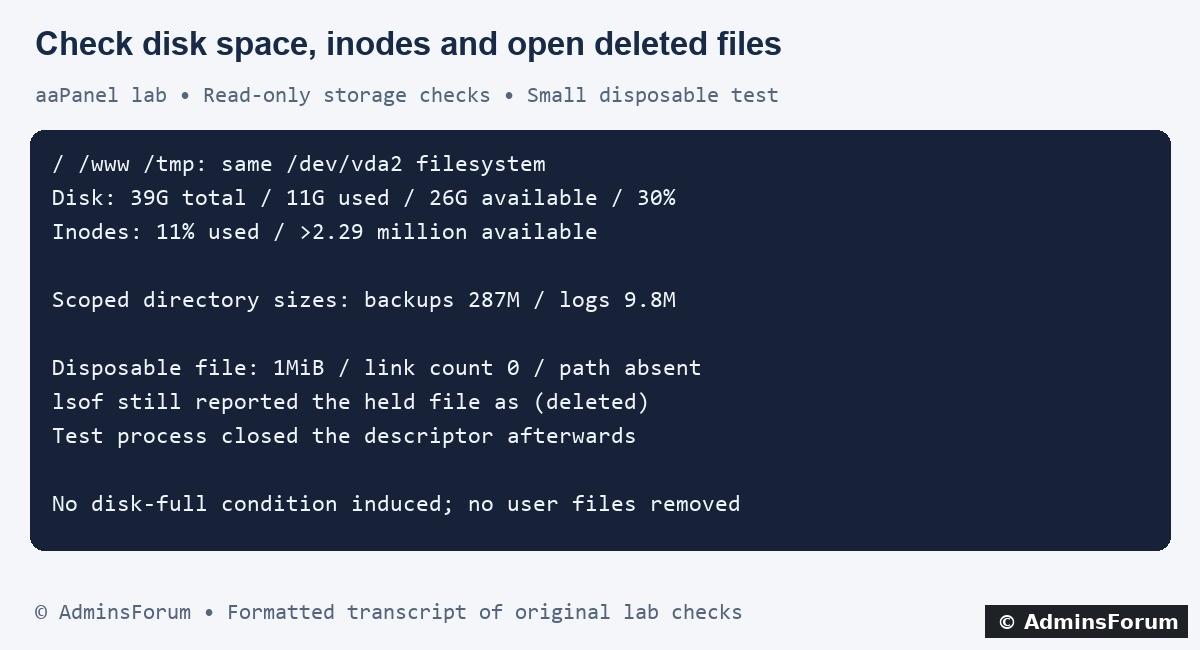
All three paths belonged to /dev/vda2, mounted at /. They therefore shared capacity; their three available values must not be added together.
The rounded disk result was 39G total, 11G used, 26G available and 30% usage. The inode snapshot showed 2,555,904 total objects, 263,510 used and 2,292,394 available, or 11% usage. Neither resource was exhausted in this lab.
For a real error, substitute the exact paths used by the failed write. Many tiny files can exhaust inodes while bytes remain, whereas a separate temporary volume may run out without filling the website's volume.
C. Measure relevant directory growth
Code:
du -x -h --max-depth=1 /www/backup /www/wwwlogs
The scoped lab results were approximately 287M for backups and 9.8M for logs. They do not explain every byte on /. We removed nothing from these directories because available capacity did not justify speculative cleanup.
Display depth limits the detail shown, not all traversal work. Large scans can cause I/O, so narrow the scope and compare growth over time. Determine which application owns the data and what its retention policy permits before removing it.
AdminsForum formatted transcript of the original checks, not a panel screenshot.
D. Why deleting a filename may not reclaim storage
Our isolated test wrote and flushed a 1MiB disposable file, unlinked its path while holding the descriptor open, and inspected only the test process. The path no longer existed, the link count was zero, and the descriptor still showed 1,048,576 allocated bytes. lsof reported the held object as (deleted).
The test process then closed the descriptor and exited, leaving no temporary data file. This demonstrates open-file behavior; it does not claim a large measured df/du discrepancy or a specific amount recoverable from a real service.
For a real investigation:
Code:
lsof -nP +L1
Inspect the relevant process and filesystem privately. The -nP options avoid resolving names/port names; +L1 selects unlinked open files. Permissions and namespaces affect visibility. Use the owning service's supported rotation/reopen or carefully planned graceful restart process rather than blindly killing it or truncating a live descriptor through /proc.
E. Recover with a deliberate retention plan
Preserve verified independent backups and useful incident evidence. Use supported log rotation, cache expiry and application maintenance tools. Identify the job creating excessive data and address it so a cleanup does not immediately get undone.
Never manually remove live database tablespaces or transaction/replication files. Avoid deleting all session files or Docker volumes as a generic cleanup. A quota, read-only filesystem or application storage limit can need a different solution even when df shows room.
After an authorized cleanup or supported expansion, repeat the checks on the same affected path, confirm a small legitimate application write and inspect fresh errors. Capacity/inode trends and growth alerts provide more useful warning than a single percentage snapshot.
Recovery workflow: a backup is proven by an isolated restore and application test.
A backup job is useful only if you can recover the right data in time. This guide builds a small recovery exercise before you automate retention or depend on a provider snapshot.
1. Define the recovery target
Write down which sites, files, databases and configuration must return. Set a recovery point target (acceptable data loss) and recovery time target. Keep a rebuild inventory separately from the VPS. Provider snapshots are convenient rollback points, but an account failure can remove the server and its snapshots together.
Choose off-site storage and a maintained backup tool such as restic. Install from a trusted supported source and read the documentation for your version/backend. Keep repository credentials and the encryption password in a recoverable secret store; losing the password can make the backup unusable.
2. Capture a consistent source
Do not copy a running database's data directory and assume it is consistent. Use a supported database dump or coordinated snapshot/backup method. Include uploads, application configuration, required secrets and rebuild information. Exclude temporary/cache data deliberately and document exclusions. A missing upload directory can matter more than a perfect OS snapshot.
For a repository already configured through protected environment/credential files, these are illustrative restic commands:
Replace the paths with the actual consistent source. Initialize a new repository only after confirming the destination; do not overwrite or repurpose one you do not understand. Run with the least privileges that can read the intended data, and examine exit codes and unreadable-file errors.
3. Restore somewhere safe
Choose an explicit snapshot from the inventory rather than assuming the newest one contains the desired state. Restore to a new empty directory on an isolated test machine:
This is a placeholder command: substitute the actual snapshot ID and a reviewed target with enough disk. Never target the production root filesystem for a practice restore. Check file contents, ownership, permissions and symlinks. Load a database dump only into an isolated test database with compatible software, then start the application and test a meaningful workflow.
4. Verify integrity and automate cautiously
A repository structural check is different from reading every stored data block, and neither replaces an application restore. Consider a scheduled data-read integrity check using the options supported by your restic release. Account for backend read/egress cost and runtime.
Record backup duration, restore duration, snapshot ID and observed data loss. Monitor the last successful backup time and check status, not just whether a scheduled process started. Send failure alerts outside the VPS. Test recovery credentials from a clean environment.
Retention warning: Forget/prune operations can permanently remove recovery points. Define retention only after restore tests, retain independent copies and review the tool's dry-run output before applying cleanup. A compromised production credential should not be able to erase every copy where the backend supports immutability or separated access.
Troubleshooting: If backups are unexpectedly small, inspect exclusions and read errors. If a restore fails, preserve the repository and read the exact error before repair or deletion. Check free space, credentials, network access and tool versions. Do not share repository passwords or unredacted file listings publicly.
How do you set up aaPanel on a new VPS?
Prepare a clean supported Linux server, install aaPanel from its official source, secure management access, install only the required web stack, and create your website. Verify DNS, HTTPS, service access and a backup restore before moving live traffic.
Review status: Documentation reviewed on 9 October 2026. A fresh-VPS installation run and original screenshots are pending. This is a preparation guide, not a claim that a specific aaPanel/OS release has been tested. Record your OS, aaPanel, web-server and PHP versions when following it.
Scope: A fresh VPS, one small PHP/static website and DNS you control. aaPanel versions, supported operating systems, installer URLs and menu labels change. Check the linked official documentation for your release before installation. This guide does not install mail, FTP or every available plugin by default.
Before starting: Keep the provider console available, verify your SSH access and take a baseline snapshot. Do not install over an existing hosting panel or production web/database stack without a supported migration plan. Never post installer output containing panel credentials or the private entrance URL.
1. Prepare a supported, clean server
Use the current aaPanel Quick Start to confirm supported OS/architecture and resource requirements. Treat the listed minimum as an installation floor, not sizing advice for your workload. Budget RAM and disk for PHP workers, the database, logs, upgrades and backups.
Patch the OS using its supported package manager and reboot if required before installing the panel. Confirm the clock is synchronized. Record which ports already have listeners. Start with the basics in 15 Things to Do After Buying a New VPS.
2. Install from the official source
Open aaPanel Quick Start and choose the intended edition and supported installation method. Read the installer prompts and any feature/licensing terms before accepting them. Use only the official installer source; do not reuse an old command copied from a blog.
Safer download handling: Download over HTTPS with certificate verification enabled, inspect the saved script and use any vendor-provided integrity/signature checks. Avoid curl -k, wget --no-check-certificate and unreviewed curl-to-shell pipelines. If TLS verification fails, check time, CA certificates and the destination rather than disabling validation. Execute a reviewed installer only on the intended server with the privileges it requires.
Save the resulting panel URL, actual port, entrance path and initial credentials in a password manager. Treat the output as sensitive. Do not assume every installation uses port 8888 or 7800.
3. Establish panel access without broad exposure
Allow the actual panel port through the provider and guest firewalls only from your management IP/VPN where practical. Preserve SSH access. Do not open a vendor example's whole port list if you are not deploying all those services.
Use the full installation-generated URL, including the entrance path. A refused connection, timeout and wrong-path 404 have different causes. Read the troubleshooting section below before changing security settings.
A first installation may use a self-signed panel certificate. Do not enter credentials through an unexplained certificate warning or switch the panel to plain HTTP. Establish trust through a verified certificate procedure or deploy a valid certificate using the vendor-supported process. Independently verify server identity and certificate details through the trusted console/provider path. Keep panel access restricted during setup.
4. Secure panel settings and trusted HTTPS
After trusted access is established, replace initial credentials with a unique password and enable supported two-factor authentication. Keep recovery information privately. Disable panel API access unless needed and scope any API credentials carefully. Configure a sensible session timeout and available security alerts.
Use a dedicated hostname such as panel.example.com with a correct DNS-only A record; publish AAAA only if management access works over IPv6. aaPanel documents Panel SSL under Settings and certificate management under Domains. Deploy a certificate matching the panel hostname, keep the chain/key private and verify renewal.
Panel SSL and website SSL are separate deployments. A certificate on your website does not automatically secure the panel. Binding a panel domain can restrict access to that hostname and block the IP path; do not enable that restriction until DNS, TLS and recovery are proven. Check the current domain access guide for your version. Avoid introducing a reverse proxy/CDN until direct access is stable; ports and real-client-IP handling matter.
5. Install only the required web stack
For a typical PHP website, choose a supported LNMP stack (Nginx, database and PHP) or LAMP if your application specifically needs Apache behavior. Select supported runtime/database versions compatible with the application. Install only necessary PHP extensions and plugins. Do not blindly choose an old PHP release to match an outdated tutorial.
Wait for installation jobs to finish and review failures in the panel. Confirm the web server, PHP-FPM and database are running. Avoid installing a second OS-packaged web/database service over the panel-managed one; conflicting listeners and paths make troubleshooting harder.
6. Create the website and application database
In Website, add the intended domain(s), choose the root directory and runtime. If needed, create a database and a dedicated application user. Save its credentials privately and give that user only the required database access; do not configure the application to use the database administrator account.
Upload trusted application files through a supported secure method. Set the running/document root to the application's public directory where required. Keep environment files, database dumps, archives and private keys outside public access. Use the application's recommended ownership/permissions, never recursive chmod 777.
Choose the supported rewrite template for your framework/CMS. Nginx does not read Apache .htaccess rules. Verify a simple static page first, then an application route and database connectivity. If you create a temporary PHP diagnostic page, restrict it and remove it after testing because it reveals configuration details.
7. Point DNS and deploy website HTTPS
Set the site's A record to the correct public IPv4 address and add AAAA only after IPv6 testing. Preserve existing mail and verification records. Read DNS Records Explained if unsure.
Verify resolution from your workstation:
Code:
dig +short A example.com
dig +short AAAA example.com
Use Website SSL or the Domains certificate manager as supported by your version. Choose a validation method you can complete. HTTP validation needs public access to the challenge path; DNS validation needs the exact TXT record or appropriately scoped DNS API access. Wildcards require DNS validation. Check CAA if issuance is denied.
After issuance, test every hostname in the certificate, the chain and automatic renewal. Enable Force HTTPS only after HTTPS works. Check for mixed content and redirect loops, particularly if a CDN is involved. Do not repeatedly retry issuance without reading the error; CA rate limits can slow recovery.
8. Expose only the intended services
A basic website generally needs public TCP 80/443. Keep management restricted and database/cache ports private. If you do not need FTP or mail, do not install them or open their ports. Review provider and panel/guest firewall rules together, including IPv6. Docker-published ports require separate review if you later add containers.
Check listeners:
Code:
sudo ss -lntup
Test a new SSH/panel session and an external website request after changes. Do not disable the entire firewall to solve a single missing rule.
9. Configure backups, jobs and alerts
Schedule both website-file and application-consistent database backups. Include required configuration, and verify the scope of aaPanel's panel/Backup Restore features rather than assuming every plugin and dependency is included. Local backups consume disk and disappear with the server; send an encrypted copy off-site with retention and limited credentials.
Restore to an isolated temporary server before relying on the backup. Check files, database contents, runtime/extensions and application behavior. Inspect overwrite warnings carefully; never test a restore by overwriting the only live copy.
Add only required application cron jobs using the intended runtime/user. Monitor disk/inodes, failed jobs, uptime, certificate expiry and backup age. Test notification delivery. Keep panel, plugins, runtime and application updates on a documented maintenance schedule.
10. Final acceptance checks
Fresh SSH and trusted panel login work through the intended management path.
The site works over HTTPS, including application routes, uploads and database operations.
Only intended ports are publicly reachable over IPv4/IPv6.
Certificate renewal and scheduled jobs are configured and monitored.
An off-site backup has been restored and checked.
A planned reboot preserves the expected services, access rules and schedules.
Troubleshooting
Panel timeout: Check the actual port, provider firewall, guest rules and listener through the console. Confirm your source IP still matches any allowlist.
Panel 404: Confirm the full entrance path and any bound-domain requirement. Do not share that path publicly.
Website shows a default page: Check DNS/proxy behavior, domain mapping and the active site's document root.
Static page works but PHP returns 502: Check the site's selected PHP version, FPM status and Nginx upstream/error log. See the Nginx 502 troubleshooting guide.
403 or permission error: Inspect the exact log, index/document-root settings, ownership and security policy. Avoid blanket permission changes.
Database connection fails: Check the application host/socket, database name/user and permissions. Keep the database private while fixing it.
Certificate fails: Read the validation log and verify DNS, challenge reachability and CAA before another attempt.
For help, include aaPanel version, OS, chosen stack, the step that failed and a redacted error. Never include panel passwords, database credentials, API tokens, private keys or full installer login output.
Common questions Can I install aaPanel alongside another hosting panel?
Use a clean supported server. Existing panels and web/database stacks can conflict; use a separate server or a supported migration plan.
Does website SSL also secure the aaPanel login?
No. Website certificates and the panel management certificate are separate. Verify the panel hostname and its certificate independently.
Which panel port should I open?
Use the actual port from your own installation output. Restrict it to your management IP or VPN where practical; do not assume a tutorial's port is correct.
DNS records connect names to services. Knowing which record to change prevents accidental website, mail and certificate outages.
Examples use example.com and documentation-only IP addresses. Replace them with your provider's real values; do not publish these examples as a working zone. DNS dashboard labels differ: @ often means the zone's root, and some dashboards append the domain to a short record name automatically.
Start with authority, not the record editor
The registrar delegates your domain to authoritative nameservers. Edit records at the DNS provider serving that delegation. A record saved at a former provider does nothing for users who query the current provider. A recursive resolver caches answers; it is not usually where you edit your zone.
Before changing anything, export/copy your current zone and record the existing nameservers. Protect registrar and DNS accounts with MFA. A DNS change can affect mail and domain verification even if your goal is only to move a website.
A — name to IPv4
Code:
example.com.      300 IN A 192.0.2.10
mail.example.com. 300 IN A 192.0.2.20
An A value is an IPv4 address, not a URL, path or port. Multiple A records can return multiple addresses, but they do not automatically provide application-aware failover. Every returned address should serve the intended workload.
AAAA — name to IPv6
Code:
example.com. 300 IN AAAA 2001:db8::10
Publish AAAA only when the service, routing and firewall work over IPv6. A stale AAAA can make a website fail for some visitors while IPv4 tests look healthy. Test both families before a migration.
CNAME — one name aliases another
Code:
www.example.com. 300 IN CNAME example.com.
The target is a hostname. A CNAME does not redirect a browser or change its URL; the web server still needs to recognize www.example.com and present a matching certificate. Avoid alias loops and unnecessarily long chains.
A conventional CNAME cannot coexist at the same name with A, MX, TXT or other ordinary data. The zone apex needs SOA/NS records, so it cannot be a conventional CNAME. Some providers offer ALIAS/ANAME or CNAME flattening; those are provider-specific features with their own behavior. Check the provider's documentation before using them.
MX — where incoming email is delivered
Code:
example.com. 300 IN MX 10 mail.example.com.
The smaller preference number is tried first. The target must be a hostname with address records, not an IP literal or a CNAME alias. Copy the complete MX set from your email provider. Changing MX does not migrate mailboxes and does not authorize outgoing email. Do not replace working hosted-mail MX records when you only move the website.
If you use an HTTP reverse proxy/CDN, the mail hostname normally needs DNS-only resolution unless that provider explicitly supplies the relevant mail proxy service.
TXT — verification and email policy data
TXT carries text used by services such as domain verification, SPF, DKIM and DMARC. The owner name and exact value both matter. Keep unrelated TXT records; adding a verification token is not a reason to delete email policy.
An illustrative SPF policy for a domain whose only authorized sender is 192.0.2.20:
Code:
example.com. 300 IN TXT "v=spf1 ip4:192.0.2.20 -all"
Do not copy this onto a real domain. Build your policy from all legitimate senders' official instructions. There must be only one SPF policy beginning v=spf1 at the evaluated name; do not add a second one for another sender. SPF also has DNS-lookup limits.
DKIM is published at the selector name provided by the sender, often as TXT or a provider-specified CNAME. DMARC belongs at _dmarc.example.com. Roll out enforcement deliberately after inspecting reports and sender alignment. DNS verification tokens are publicly readable; never put passwords or API secrets in TXT.
NS — which nameservers are authoritative
Changing the registrar's nameservers moves delegation. Adding NS entries in an arbitrary DNS dashboard is not a substitute for that registrar change. NS records can also delegate a subdomain to another DNS service.
Before switching providers, copy all required A/AAAA, MX, TXT, CAA and other records to the new zone. Check DNSSEC and the registrar's DS record with both providers; an incompatible stale DS can cause validating resolvers to return SERVFAIL. Follow a documented DNSSEC migration plan rather than randomly toggling it. In-zone nameserver hostnames may require registrar glue records.
PTR — IP address back to a name
PTR lives in a reverse-DNS zone, usually controlled by the VPS/IP provider. An ordinary PTR you add to example.com's forward zone does not change public reverse DNS for your VPS address.
For a mail server, arrange a meaningful PTR and corresponding forward address record as required by your provider and mail setup. PTR is one part of deliverability; it does not guarantee good reputation or inbox placement.
CAA — constrain certificate issuance
An example permitting Let's Encrypt:
Code:
example.com. 300 IN CAA 0 issue "letsencrypt.org"
Use the actual CA identifiers required by your certificate/CDN provider. issue controls normal issuance; issuewild can set a separate wildcard policy. CAA lookup rules can involve parent domains and aliases, so examine the effective policy rather than one dashboard row. A restrictive CAA policy can break a future renewal if your provider uses another CA. CAA does not install TLS, revoke an existing certificate or remove a CA's normal domain-validation requirements.
TTL — how long answers may be cached
TTL is expressed in seconds. A 300-second TTL is five minutes, but changing a TTL does not purge answers already cached under the old value. Lower the TTL sufficiently before a planned migration, keep the old service available during the overlap, and restore a normal value afterward. Negative answers and delegation can have different cache lifetimes. There is no single guaranteed "propagation time" for every DNS change.
Read-only checks with dig
Run from a workstation with dig installed; Ubuntu/Debian package it in dnsutils:
Use normal dig output too when you need status codes; +short alone hides useful context. Query a nameserver returned by the NS lookup to compare authoritative data with a resolver's cached answer:
Code:
dig @YOUR_AUTHORITATIVE_NAMESERVER example.com A +noall +answer
 dig @1.1.1.1 example.com A +noall +answer
Do not use ANY as a reliable inventory of a zone. Export records from the provider instead.
Troubleshooting decision points
Old address still appears: Compare the active authoritative server with recursive resolvers. Check delegation, the old TTL and whether you edited the right zone.
NXDOMAIN: The queried name does not exist according to the answer. Check spelling, duplicated domain suffixes and negative caching. NOERROR with no answer can mean the name exists but that record type does not.
SERVFAIL: Investigate authoritative availability, delegation and DNSSEC; do not assume waiting will fix it.
Only IPv6 users fail: Compare AAAA with the service's actual IPv6 reachability.
Mail broke after moving the website: Check preserved MX, mail-host address records, SPF/DKIM/DMARC and provider proxy settings.
Certificate issuance fails: Check public DNS, CAA and the actual validation method (HTTP or DNS challenge). Do not weaken TLS validation to hide the symptom.
When asking for help, give the affected public hostname, expected record type, DNS provider and a sanitized dig response. Keep account credentials and private information out of the post.
Hardening a VPS is an ongoing process: reduce exposed services, protect administrator access, keep software supported and make recovery verifiable. This checklist gives you evidence to collect, not just settings to copy.
Scope: Examples target systemd-based Ubuntu/Debian. Adapt package, service and firewall commands for other distributions. On a hosting-panel server, follow vendor-supported procedures so panel updates do not undo your changes.
Safety first: Test the provider console, save configuration backups and keep your current SSH session open. Make one access-control change at a time and confirm a second login works. Never use your only production server to experiment with an unreviewed hardening script.
1. Protect the account that owns the VPS
Enable MFA on the provider, registrar, DNS and backup accounts. Store recovery codes securely and use unique passwords. Review API tokens, team access and billing/contact recovery paths. A hardened guest cannot prevent an attacker with provider-console access from replacing its disks.
Verify: Remove obsolete users/tokens, test your recovery procedure and confirm security notifications go to a monitored address.
2. Inventory users, services and public listeners
Code:
cat /etc/os-release
getent passwd
getent group sudo
sudo ss -lntup
systemctl --failed
systemctl list-unit-files --state=enabled
Review human users, service accounts and privileged groups. Do not delete unfamiliar system accounts without understanding their purpose. Bind database/cache services to loopback or the required private interface. Remove obsolete software after checking dependencies.
Verify: From an external machine you control, test only your server's intended ports. Check IPv4 and IPv6; a local listener list alone does not prove what the Internet can reach.
3. Use named admins and tested SSH keys
Each administrator should have their own account/key so access can be revoked individually. Protect private keys with a passphrase and keep them off the server. Confirm key login and sudo in a new session before disabling any existing method.
For a standalone server where keyboard-interactive MFA is not used, the intended SSH policy may include:
Code:
PermitRootLogin no
PubkeyAuthentication yes
PasswordAuthentication no
KbdInteractiveAuthentication no
Back up the configuration and edit the effective file/snippet with sudoedit. Inspect Include order, provider snippets and Match blocks. Validate and review before reloading:
If syntax is valid, use the appropriate reload mechanism; commonly sudo systemctl reload ssh on Ubuntu/Debian. Then test a fresh login. For conditional Match blocks, inspect the actual user/client context with sshd -T -C. Do not disable keyboard-interactive if your intended MFA depends on it.
Verify: Your named admin can log in and use sudo; root/password access behaves as intended. Keep the console available until all checks pass.
4. Restrict management access at both firewall layers
Use the provider firewall and a supported guest firewall. Permit your actual SSH port before enabling restrictions. Prefer a VPN or trusted source addresses for SSH and panel interfaces; account for a changing home IP and recovery access. Expose web ports only for services that need them. Do not expose database, Redis or Docker management endpoints publicly.
For an existing UFW deployment, inspect without changing policy:
Code:
sudo ufw status verbose
sudo ufw status numbered
Do not layer UFW over a panel-managed firewall without checking compatibility. Review IPv6 and Docker forwarding/published-port behavior separately.
Verify: Fresh management connections succeed from approved paths and unintended public ports are unreachable. A hidden panel URL or custom SSH port is not an authentication control.
5. Patch every software layer
Track the OS, kernel, panel, plugins, PHP/runtime versions, web apps and dependencies. Remove end-of-life versions or plan a supported migration. Review updates and backups before applying them:
Code:
sudo apt update
apt list --upgradable
Use automatic security updates where supported, but confirm allowed repositories, logs, failure alerts and reboot policy. Third-party software may require a separate update process. Schedule and verify reboots when needed; installing a kernel update does not mean the running kernel changed.
Verify: Update jobs finish successfully, notifications arrive and the application still works after maintenance.
6. Protect hosting panels and applications
Use a valid TLS certificate, unique admin credentials and supported MFA. Restrict panel access and disable unused plugins/API access. Give applications separate database users with only needed privileges. Keep secrets outside public web roots and avoid storing them in repositories or world-readable files.
Do not solve ownership errors with recursive chmod 777. Do not disable SELinux/AppArmor to make an application start; examine the denial and adjust the intended policy. Validate application-specific permissions and test uploads, scheduled jobs and updates afterward.
Verify: The panel is reachable only through intended paths; TLS validates without bypassing warnings; application accounts cannot access unrelated databases/files.
7. Treat brute-force protection as an extra layer
Fail2ban or an equivalent tool can help with services that still need public login endpoints. Verify the selected filter reads the actual log/journal and the ban action uses your active firewall. Account for reverse proxies so legitimate visitors are not all attributed to the proxy's IP. Use supported real-client-IP configuration and trusted proxy ranges.
Verify: Inspect service status, configuration checks and jail counters using the installed tool's documentation. Keep a console and recovery path for accidental bans. Rate limiting does not replace keys, MFA or timely patching.
8. Make detection useful
Monitor unexpected successful logins, privileged changes, new listeners, failed update/backup jobs and resource exhaustion. Retain logs long enough to investigate and consider a protected off-server copy. Basic inspection:
Service/log names vary; also inspect application and panel audit logs. Failed SSH attempts are common on public hosts. An unfamiliar successful login or a changed authorized_keys file deserves investigation.
Verify: Trigger a harmless test alert and confirm someone receives it. Redact IPs, usernames and personal data before sharing logs publicly.
9. Keep independent, tested backups
Use encrypted off-site backups, retention and credentials with limited scope. Include application-consistent database backups, files, configuration and rebuild instructions. Protect at least one copy from deletion by a compromised production server where feasible. A snapshot under the same provider account is useful, but shares that account's failure risk.
Verify: Restore into an isolated environment and test the application. Record how much data/time recovery would lose. Monitor backup age and restore failures.
10. Prepare for compromise before it happens
Keep a private inventory, contacts and rebuild plan. If compromise is suspected, use the provider console/trusted workstation, preserve relevant evidence and isolate the affected system as appropriate. Do not assume deleting one suspicious file makes the host trustworthy. Plan to rebuild from a known-good image and rotate exposed credentials from a clean device after containment. Check adjacent provider, DNS, backup and application accounts too.
Monthly review: Are all administrators still authorized? Are OS/apps supported? Are only necessary ports exposed? Do alerts arrive? Has a restore been tested? Repeat after major deployments or staff changes.
A 502 Bad Gateway means a gateway did not receive a usable response from its upstream. Fix the failed link in the request path rather than repeatedly restarting the whole server.
Scope: This guide covers Nginx in front of PHP-FPM or an HTTP application on Linux. Commands assume a conventional systemd installation. Panel-managed Nginx may have different binaries, paths and service names; use the panel's supported configuration tools and logs. Back up the affected configuration before editing. Never share unredacted nginx -T output: configuration can contain secrets.
1. Identify which layer returns the error
Write down the failing URL, time, request method and whether all pages fail or only one application. A CDN, load balancer, Nginx or the application itself can return 502. Response branding and headers are clues, not proof. Correlate the same request with each layer's logs.
Use a real, safe URL; do not replay payments or other state-changing requests. If authorized to test the origin directly, preserve the hostname and TLS validation:
Do not add -k to hide a certificate problem. An origin restricted to the CDN may correctly reject your workstation.
2. Read the matching error log
Find the error_log directive for the affected virtual host. /var/log/nginx/error.log is a common package default, not a universal path:
Inspect nginx -T locally if you need to locate the active server block, proxy_pass or fastcgi_pass. Ensure you are using the binary/configuration that the running service actually uses. Note the upstream address and exact error.
Connection refused: The target port/socket has no accepting service, or a device actively rejects it. Check process health and listener address.
No such file or directory: A Unix socket path is wrong or the expected socket was never created.
Permission denied: Check socket and parent-directory access plus SELinux/AppArmor denials.
Upstream sent invalid header / too big header: Inspect backend output, cookies and response headers. Protocol mismatch or oversized headers needs a specific fix.
Upstream timed out: Investigate slow or overloaded dependencies. This often produces 504; error-page mappings and intermediate gateways can change the displayed status.
Look for an OOM kill, exhausted disk/inodes, a crash loop or a deployment at the same timestamp. Confirm the backend's service name before inspecting its status and journal. Restart only the affected service after capturing evidence and understanding the impact; repeated restarts can hide the cause and interrupt healthy requests.
4. PHP-FPM: make the listener and fastcgi_pass agree
A PHP version change commonly leaves Nginx pointing at an old socket. Discover your installed FPM units instead of assuming a PHP version:
Code:
systemctl list-units --all --type=service 'php*-fpm.service'
ls -l /run/php/
Inspect the selected FPM pool's listen setting and the site's fastcgi_pass. These are alternative examples, not values to paste blindly:
Code:
# Unix socket example
fastcgi_pass unix:/run/php/php8.3-fpm.sock;

# TCP listener example
fastcgi_pass 127.0.0.1:9000;
Use the actual path/address, and keep FPM on a private interface. Port 9000 is FastCGI, not HTTP: curl to it is not a valid application health check. Verify that the Nginx worker identity can traverse the socket's parent directories and access the socket. Correct FPM listen.owner, listen.group and listen.mode as appropriate for your deployment; a manual chmod may disappear when FPM recreates the socket.
Do not use chmod 777 or disable SELinux/AppArmor. If discretionary permissions look correct, inspect security-policy denials. If FPM logs show pm.max_children saturation, measure worker memory and request duration before changing limits. More workers can trigger OOM on a small VPS. Also inspect database latency and slow requests.
5. HTTP applications: test the configured endpoint locally
For an application intentionally listening on loopback TCP 3000:
Replace the port/path with the real endpoint. If it requires a Host header, include the expected hostname. If this fails, fix the backend before editing Nginx. If it succeeds, compare the endpoint with proxy_pass and check whether the backend expects HTTP or HTTPS. Preserve certificate validation and configure upstream SNI/trust correctly for HTTPS.
Inside a container, 127.0.0.1 means that container, not another container or the host. Verify service DNS names, networks and listeners from the Nginx container's context. Avoid publishing an internal application port to the Internet as a troubleshooting shortcut.
6. Check changes and limits without guesswork
If the backend is reachable but only large/login responses fail, inspect the exact header/buffer error and backend response. Fix oversized cookies or abnormal headers first. Change proxy/FastCGI buffer directives only for the relevant site with a measured requirement.
If requests are slow, inspect application, database and external API timing before raising proxy_read_timeout or fastcgi_read_timeout. Those read timeouts concern inactivity between reads, not a universal total-request deadline. Raising them cannot repair a dead listener and may keep scarce workers occupied longer. Prefer background jobs for long-running work.
7. Apply one fix and verify it
After a backed-up configuration edit:
Code:
sudo nginx -t
Only if the test succeeds, reload using the deployment's supported mechanism. On a conventional package installation:
Code:
sudo systemctl reload nginx
Test the affected endpoint and a normal page again, check the logs for fresh errors and watch the backend under realistic traffic. A successful syntax check does not prove the upstream works. If the change fails, restore the saved configuration, validate it and reload. On panels, keep persistent changes in the supported template/settings so regeneration does not overwrite them.
When asking for help, include: OS, panel/container details, Nginx/PHP/app versions, the relevant redacted error line, whether static/PHP/all routes fail, the configured upstream type and the last change before failure. Remove tokens, private keys, credentials and user data from logs/configuration.
What should you do first after buying a VPS?
Confirm recovery-console access, update the OS, create a named administrator with SSH keys, allow only the required ports, and set up off-site backups. Verify a fresh login and a restore before installing a hosting panel or moving a live website.
Review status: Documentation reviewed on 9 October 2026. Fresh-VPS walkthrough testing and original screenshots are pending; no OS or panel version is claimed as hands-on tested. Record your exact release with cat /etc/os-release before using these examples.
Scope: Commands below target a fresh, systemd-based Ubuntu/Debian VPS. AlmaLinux/Rocky use different package and firewall tools; do not paste these commands there. Use a supported OS release. If a control panel is already installed, follow its supported update, firewall and backup procedures.
Before you start: Keep your current SSH session open and confirm the provider's web/serial console works. Replace YOUR_SERVER_IP and adminuser with your own values. Run sudo commands as a sudo-capable user; on an initial root session, omit sudo. Never paste passwords, private SSH keys or access tokens into a forum post.
1. Check what you actually bought
Verify the IP addresses, RAM, storage, bandwidth allowance, virtualization type, renewal cost and backup options in the provider dashboard. Check that the guest matches the plan:
A disk advertised by the provider and the usable filesystem size can differ. Investigate an unexpectedly small filesystem before storing data; do not resize partitions blindly.
2. Establish a recovery path
Open the provider console before changing SSH or firewall settings. Know how rescue mode works and record the server ID and support contact in a private runbook. Take a baseline snapshot if available. Snapshots on the same provider are convenient rollback points, but they are not an independent backup.
3. Verify the SSH host key
On first connection, compare the host-key fingerprint with one obtained through the provider console or another trusted provider channel. In the server console:
Use the initial username specified by your provider if it is not root. A changed host-key warning may follow a reinstall, but can also indicate an attack. Investigate it before accepting a replacement key; do not simply erase the warning.
4. Patch the fresh operating system
Code:
sudo apt update
apt list --upgradable
sudo apt upgrade
Read the proposed changes and configuration-file prompts. Do not force an unattended upgrade on a server you have not inspected. If the system reports a required reboot, schedule one while the console is available, then reconnect and check services. Do not treat a routine package upgrade as a distribution upgrade.
5. Create a named administrator
Use a personal account for daily work and sudo for privileged tasks:
Set a strong, unique local password when prompted. Log in as that user in a second session and verify:
Code:
whoami
sudo -v
sudo id
Do not remove the original access method until the new account and sudo both work.
6. Set up an SSH key from your own computer
On a computer with OpenSSH installed, generate a key only if you do not already have a suitable one. Choose a new filename if prompted about overwriting an existing key, and protect it with a passphrase:
Use -p with the actual SSH port if it differs from 22. If ssh-copy-id is unavailable, install only the public .pub key in the user's ~/.ssh/authorized_keys through your trusted console/login. The .ssh directory should be owned by that user with mode 700, and authorized_keys with mode 600. The private key stays on your computer.
7. Harden SSH without locking yourself out Do this only after a fresh key-based login and sudo have succeeded. Back up the SSH configuration, including any snippets, and inspect /etc/ssh/sshd_config and /etc/ssh/sshd_config.d/. Provider/cloud-init snippets and Match blocks can affect the result.
Use sudoedit to update the configuration file that actually controls these settings:
Code:
PermitRootLogin no
PubkeyAuthentication yes
PasswordAuthentication no
KbdInteractiveAuthentication no
The last setting disables keyboard-interactive authentication; do not disable it if your planned MFA uses that method. Validate syntax and inspect effective settings before reloading:
If syntax validation fails, correct it before reloading. sshd generally uses the first obtained value for a setting, so adding a later snippet may not override an earlier one. For Match rules, also check the intended user/client context with sshd -T -C (see man sshd). Open another fresh connection to confirm the intended authentication policy. Keep the original session until that works. A custom port reduces log noise; it is not a substitute for keys and access controls.
8. Configure both firewall layers
Check the provider/cloud firewall as well as the guest firewall. Allow your actual SSH port before enabling either. The following UFW example assumes SSH really listens on TCP 22 and a fresh server without Docker or a panel-managed firewall:
For a web server, add TCP 80 and 443 only when required. Avoid exposing database, Redis or panel ports to the whole Internet; prefer loopback, a VPN or restricted source addresses. Apply and test IPv6 rules too if IPv6 is enabled. Docker-published ports need separate attention because their traffic may bypass normal UFW expectations. After every change, test a new SSH connection. If locked out, use the provider console to repair the relevant rule; repeatedly reconnecting will not fix a blocked port.
9. Set a useful hostname and verify time
Pick a hostname you control, such as vps1.example.com:
Code:
sudo hostnamectl set-hostname vps1.example.com
hostnamectl
timedatectl status
Check /etc/hosts and provider/cloud-init behavior if the name reverts after reboot. A hostname change does not create a DNS record. UTC is convenient for servers; use sudo timedatectl set-timezone UTC if that suits your operations. Verify an NTP service is actually synchronizing rather than assuming the displayed time is correct. Bad time can break TLS checks, authentication and useful log correlation.
10. Plan DNS before moving traffic
Create an A record for the public IPv4 address. Add AAAA only after IPv6 routing, firewall rules and the service have been tested. Check resolution from your workstation and an external network:
Code:
dig +short A vps1.example.com
dig +short AAAA vps1.example.com
If dig is missing on Ubuntu/Debian, it is supplied by dnsutils. Allow for DNS caching. Reverse DNS (PTR) is usually set in the provider dashboard and matters especially for mail. Do not deploy a mail server before checking outbound port restrictions and SPF/DKIM/DMARC requirements.
11. Inspect listening services before adding more
Code:
sudo ss -lntup
systemctl --failed
systemctl list-unit-files --state=enabled
Understand every public listener. Bind internal services to loopback/private networks and remove unneeded software only after checking dependencies. Install a control panel only on an OS and clean-server setup supported by its vendor. Verify installers against the vendor's official instructions; do not run a random downloaded script as root. Keep SELinux/AppArmor enabled and troubleshoot policy denials instead of disabling protection as a shortcut.
12. Configure automatic security updates deliberately
Ubuntu commonly includes unattended-upgrades, but provider images vary. Check your own configuration:
Review /etc/apt/apt.conf.d/50unattended-upgrades and the periodic-update configuration. Confirm which repositories are covered, how failures are reported and whether automatic reboot is enabled. Third-party repositories are not automatically covered just because they were added. For panel-managed systems, check vendor compatibility first and schedule required reboots.
13. Add monitoring and actionable alerts
Monitor external availability, disk space and inodes, memory pressure, CPU, failed services, certificate expiry and backup failures. Start with a baseline:
Test the alert delivery path. An alert stored only on the failed VPS is not useful. Low "free" RAM alone is not a problem: Linux uses memory for cache, so examine available memory, swap activity and application symptoms. Sustained resource pressure needs investigation, not an automatic reboot or blind tuning.
14. Build off-site backups and prove a restore
Back up application data, database dumps, configuration and the information needed to rebuild. Store an encrypted copy outside this VPS/provider account, protect backup credentials and define retention. Database backups need application-consistent dumps or a supported snapshot/quiescing process; copying live database files can produce an unusable backup.
Restore into an isolated temporary environment. Verify files, ownership, database contents and that the application starts. Record the recovery point objective (how much data you can lose) and recovery time objective (how long recovery may take). A successful upload or a provider snapshot alone does not prove recoverability.
15. Reboot, retest and write a private runbook
Once access and backups are ready, do a planned reboot from the console or with sudo reboot. Confirm SSH, firewall policy, DNS, expected services, monitoring and backup schedules survive it. Record the OS version, purpose, ports, update schedule, backup location and recovery steps. Store secrets in a password manager, not in the runbook or forum.
Useful troubleshooting shortcuts
SSH times out: Check the correct IP/port, provider firewall, UFW, routing and service listener through the console. Test IPv4 and IPv6 separately.
Connection refused: Check sudo systemctl status ssh and sudo ss -lntp. The host may be reachable but nothing is listening on that port.
Permission denied (publickey): Check the username, chosen key, ownership/modes and server logs. Use ssh -v from your computer; redact identifying details before sharing output.
Updates fail: Check disk/inodes, DNS, clock and repository errors. Wait for legitimate package jobs to finish; do not delete package-manager lock files to force access.
Website fails only on some networks: Check stale DNS and a broken AAAA record before changing the web server.
Done means verified: a fresh key-based administrator login works, only intended ports are reachable, updates are covered, alerts arrive, and an off-site backup has been restored successfully.
What OS and workload are you setting up? Share the non-sensitive details if you need help adapting this checklist.
Final verification checklist
Provider recovery console opens and the server identity is verified.
A fresh SSH-key login as your named administrator works, with sudo access.
Only intended services are reachable through both firewall layers.
OS update policy, DNS and time synchronization are checked.
Monitoring alerts reach you outside the VPS.
An off-site backup has been restored in an isolated environment.
The access, services and scheduled jobs still work after a planned reboot.
Common questions Should I install aaPanel before doing this checklist?
Prepare and verify the fresh VPS first. Then check aaPanel's current OS requirements and use its supported installation and firewall procedures.
Is a provider snapshot enough as my only backup?
No. Keep an independent copy outside the VPS and test a restore. A snapshot is useful for rollback but can share the same account or provider failure.
Do I need to change SSH port 22?
Changing the port can reduce log noise, but keys, tested access controls and a recovery path matter more. Allow and verify the actual port before changing firewall rules.
cPanel licence prices keep going up and I'm planning to move my sites to a free panel. For anyone who has done it: what's the smoothest way?
What has worked for most people:
Pick the target panel first, based on what you actually use (do you need email on the server? which PHP versions?). See the comparison thread in this forum.
Take full cPanel backups of each account (Backup Wizard), plus separate database dumps as a safety net.
Check for an importer. Some panels can import cPanel backups directly; CyberPanel and HestiaCP have tools for this. Test with one small account first.
For everything else, move manually: files with rsync, databases with mysqldump, then recreate email accounts and DNS records.
Lower DNS TTL beforehand, test each site on the new server through your hosts file, then switch DNS.
Email is the hardest part. Move mailboxes with an IMAP sync tool, and keep the old server running for a few days so nothing is lost while DNS updates.
Please share which panel you moved to and any problems you hit along the way.
Beyond the big names, these panels each fit a particular kind of setup:
Webmin and Virtualmin: Webmin is a long-running, open-source web interface for administering a Linux system. Virtualmin adds virtual hosting on top (sites, mail, DNS, databases). Very flexible; the interface is busier than newer panels.
ISPConfig: open-source and built for multi-server setups, where web, mail, DNS and databases can run on separate machines managed from one panel.
Froxlor: a lightweight open-source panel for hosting providers and small setups, configured mostly through its web interface.
KeyHelp: a free (not open-source) panel from a German hosting company, with a clean interface and mail, DNS and backups included.
Coolify: not a classic hosting panel but an open-source, self-hosted platform for deploying apps, databases and services with Docker. A good fit for developers who want a Heroku-style workflow on their own server.
Use this forum for questions about any of these, or about any other free panel not listed. Please mention the panel name and version in your thread title.