



“No space left on device” can mean exhausted bytes, inodes, quota or a different filesystem than the one you checked. Diagnose the constraint before deleting logs or backups.
1. Find the affected mount
These read-only commands target GNU/Linux:
Replace /var/log with the directory where writes fail. A separate /var, container layer or network mount may be full while / has space. Check the application user's quota if the filesystem has room. Reserved blocks can make space unavailable to an ordinary service account.
2. Measure usage without crossing mounts
The -x option keeps the walk on one filesystem; -d1 summarizes one directory level. On a busy host, scans can cause I/O, so inspect one plausible directory at a time. Check application uploads, backup retention, caches and database logs. Hidden directories count too; a shell wildcard can miss them.
3. Explain a df/du mismatch
A removed file can still occupy space while a process holds it open. If lsof is installed:
Inspect the process and mount associated with large deleted files. Arrange a supported log reopen or targeted service restart after assessing impact. Do not kill processes blindly. Other differences include snapshots, filesystem metadata, sparse files, inaccessible directories and files hidden beneath mount points.
4. Reclaim the right data
Preserve incident evidence and verified backups first. Use the application's supported cache/log retention mechanism. Preview package or container cleanup and understand what it removes; Docker volumes can contain the only database copy. Never delete active database files or blindly run broad recursive removal commands.
If inodes are exhausted, investigate directories containing very many tiny files and fix their retention. If bytes are exhausted, identify the largest growing sources. Deleting one old archive without fixing an endless log loop buys only temporary relief. Avoid manually truncating a log when the application expects a different rotation process.
5. Validate recovery and prevent recurrence
Repeat df -h and df -i for the affected path, confirm the service can write, and check for database/application errors caused by the outage. Alert on both byte and inode availability with enough lead time. Budget local backup staging and update space. Track growth rather than relying on a single percentage threshold.
When asking for help: Share the failing path, filesystem type and sanitized df/du summaries. Avoid exposing customer filenames or secrets. If a filesystem turned read-only, inspect kernel/storage errors; deleting files is not the appropriate fix.
Reference: df manual and your installed man du/man lsof documentation.
aaPanel lab walkthrough: storage checks and a deleted-open-file demonstration
Verified 14 October 2026 on aaPanel Free 8.0.7 and Ubuntu 22.04.5. This extends the Linux procedure above with original lab measurements. The server had available space; we did not fill its disk or reproduce a disk-full outage.
A. Start from the path that could not be written
Check aaPanel Home's disk indicator as an initial clue, then use a private SSH or panel Terminal session to inspect the actual application, database, backup or temporary path. A headline root-disk percentage does not identify every separate filesystem.
For a website issue, match the failed operation with the access/error/application logs. Distinguish an exhausted resource from permission denial or a filesystem that became read-only before choosing a repair.
B. Check bytes and inodes for the relevant paths
Our read-only checks were:
All three paths belonged to /dev/vda2, mounted at /. They therefore shared capacity; their three available values must not be added together.
The rounded disk result was 39G total, 11G used, 26G available and 30% usage. The inode snapshot showed 2,555,904 total objects, 263,510 used and 2,292,394 available, or 11% usage. Neither resource was exhausted in this lab.
For a real error, substitute the exact paths used by the failed write. Many tiny files can exhaust inodes while bytes remain, whereas a separate temporary volume may run out without filling the website's volume.
C. Measure relevant directory growth
The scoped lab results were approximately 287M for backups and 9.8M for logs. They do not explain every byte on /. We removed nothing from these directories because available capacity did not justify speculative cleanup.
Display depth limits the detail shown, not all traversal work. Large scans can cause I/O, so narrow the scope and compare growth over time. Determine which application owns the data and what its retention policy permits before removing it.
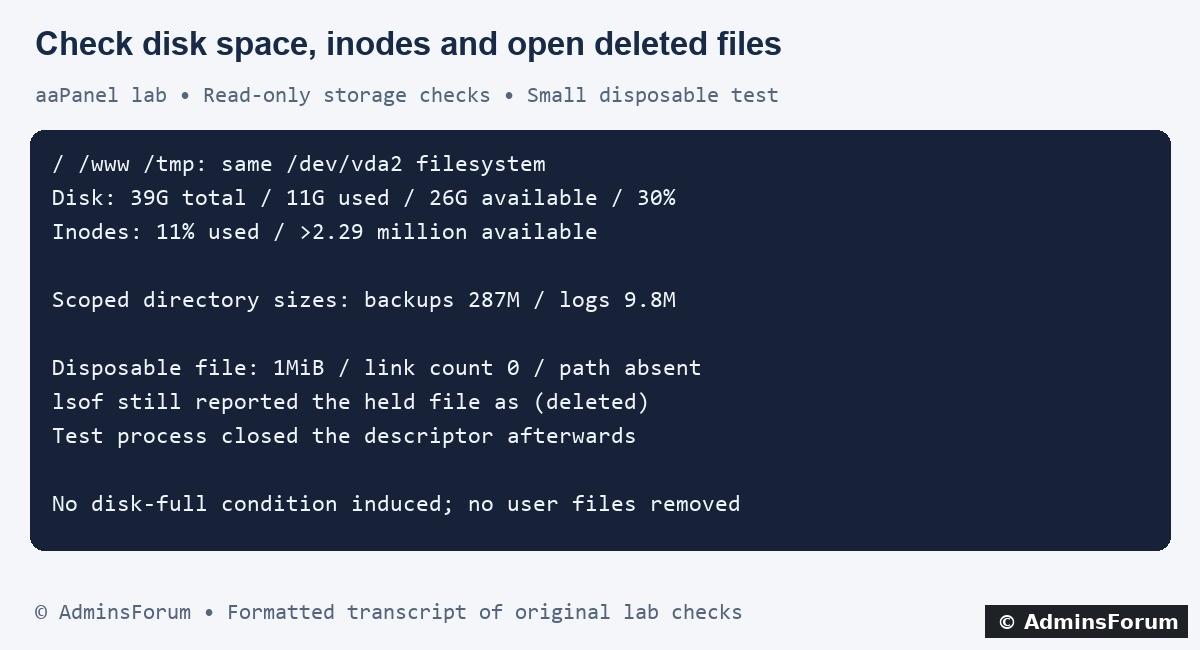
AdminsForum formatted transcript of the original checks, not a panel screenshot.
D. Why deleting a filename may not reclaim storage
Our isolated test wrote and flushed a 1MiB disposable file, unlinked its path while holding the descriptor open, and inspected only the test process. The path no longer existed, the link count was zero, and the descriptor still showed 1,048,576 allocated bytes. lsof reported the held object as (deleted).
The test process then closed the descriptor and exited, leaving no temporary data file. This demonstrates open-file behavior; it does not claim a large measured df/du discrepancy or a specific amount recoverable from a real service.
For a real investigation:
Inspect the relevant process and filesystem privately. The -nP options avoid resolving names/port names; +L1 selects unlinked open files. Permissions and namespaces affect visibility. Use the owning service's supported rotation/reopen or carefully planned graceful restart process rather than blindly killing it or truncating a live descriptor through /proc.
E. Recover with a deliberate retention plan
Preserve verified independent backups and useful incident evidence. Use supported log rotation, cache expiry and application maintenance tools. Identify the job creating excessive data and address it so a cleanup does not immediately get undone.
Never manually remove live database tablespaces or transaction/replication files. Avoid deleting all session files or Docker volumes as a generic cleanup. A quota, read-only filesystem or application storage limit can need a different solution even when df shows room.
After an authorized cleanup or supported expansion, repeat the checks on the same affected path, confirm a small legitimate application write and inspect fresh errors. Capacity/inode trends and growth alerts provide more useful warning than a single percentage snapshot.
Additional references: GNU df, GNU du and lsof manual.
1. Find the affected mount
These read-only commands target GNU/Linux:
Code:
df -hT
df -i
findmnt -T /var/log2. Measure usage without crossing mounts
Code:
sudo du -xhd1 /var
sudo du -xhd1 /var/log
sudo journalctl --disk-usage3. Explain a df/du mismatch
A removed file can still occupy space while a process holds it open. If lsof is installed:
Code:
sudo lsof +L14. Reclaim the right data
Preserve incident evidence and verified backups first. Use the application's supported cache/log retention mechanism. Preview package or container cleanup and understand what it removes; Docker volumes can contain the only database copy. Never delete active database files or blindly run broad recursive removal commands.
If inodes are exhausted, investigate directories containing very many tiny files and fix their retention. If bytes are exhausted, identify the largest growing sources. Deleting one old archive without fixing an endless log loop buys only temporary relief. Avoid manually truncating a log when the application expects a different rotation process.
5. Validate recovery and prevent recurrence
Repeat df -h and df -i for the affected path, confirm the service can write, and check for database/application errors caused by the outage. Alert on both byte and inode availability with enough lead time. Budget local backup staging and update space. Track growth rather than relying on a single percentage threshold.
When asking for help: Share the failing path, filesystem type and sanitized df/du summaries. Avoid exposing customer filenames or secrets. If a filesystem turned read-only, inspect kernel/storage errors; deleting files is not the appropriate fix.
Reference: df manual and your installed man du/man lsof documentation.
aaPanel lab walkthrough: storage checks and a deleted-open-file demonstration
Verified 14 October 2026 on aaPanel Free 8.0.7 and Ubuntu 22.04.5. This extends the Linux procedure above with original lab measurements. The server had available space; we did not fill its disk or reproduce a disk-full outage.
A. Start from the path that could not be written
Check aaPanel Home's disk indicator as an initial clue, then use a private SSH or panel Terminal session to inspect the actual application, database, backup or temporary path. A headline root-disk percentage does not identify every separate filesystem.
For a website issue, match the failed operation with the access/error/application logs. Distinguish an exhausted resource from permission denial or a filesystem that became read-only before choosing a repair.
B. Check bytes and inodes for the relevant paths
Our read-only checks were:
Code:
df -h / /www /tmp
df -i / /www /tmpThe rounded disk result was 39G total, 11G used, 26G available and 30% usage. The inode snapshot showed 2,555,904 total objects, 263,510 used and 2,292,394 available, or 11% usage. Neither resource was exhausted in this lab.
For a real error, substitute the exact paths used by the failed write. Many tiny files can exhaust inodes while bytes remain, whereas a separate temporary volume may run out without filling the website's volume.
C. Measure relevant directory growth
Code:
du -x -h --max-depth=1 /www/backup /www/wwwlogsDisplay depth limits the detail shown, not all traversal work. Large scans can cause I/O, so narrow the scope and compare growth over time. Determine which application owns the data and what its retention policy permits before removing it.
AdminsForum formatted transcript of the original checks, not a panel screenshot.
D. Why deleting a filename may not reclaim storage
Our isolated test wrote and flushed a 1MiB disposable file, unlinked its path while holding the descriptor open, and inspected only the test process. The path no longer existed, the link count was zero, and the descriptor still showed 1,048,576 allocated bytes. lsof reported the held object as (deleted).
The test process then closed the descriptor and exited, leaving no temporary data file. This demonstrates open-file behavior; it does not claim a large measured df/du discrepancy or a specific amount recoverable from a real service.
For a real investigation:
Code:
lsof -nP +L1E. Recover with a deliberate retention plan
Preserve verified independent backups and useful incident evidence. Use supported log rotation, cache expiry and application maintenance tools. Identify the job creating excessive data and address it so a cleanup does not immediately get undone.
Never manually remove live database tablespaces or transaction/replication files. Avoid deleting all session files or Docker volumes as a generic cleanup. A quota, read-only filesystem or application storage limit can need a different solution even when df shows room.
After an authorized cleanup or supported expansion, repeat the checks on the same affected path, confirm a small legitimate application write and inspect fresh errors. Capacity/inode trends and growth alerts provide more useful warning than a single percentage snapshot.
Additional references: GNU df, GNU du and lsof manual.